Category: Articles

  • Business Acumen: The 9 Human Efficiency Losses

    Business Acumen: The 9 Human Efficiency Losses

    The equipment losses are about how the machines run. These are about how the people work. Same waterfall, completely different fix. 

    If the 11 equipment losses are where reliability work pays off, the 9 human efficiency losses are where it doesn’t. That’s the single most important thing to understand about this category: these losses mirror the equipment ones, but you don’t solve them with maintenance. You solve them with planning, organization, training, and better physical layout. Throw a reliability program at a planning problem and you’ll spend money fixing machines that were never the issue. 

    These nine split into three scheduled labor losses and six others. 

    The three scheduled labor losses 

    These are the labor side of your planned downtime. The equipment was supposed to be down; the question is whether the people were used well while it was. 

    1. Scheduled Maintenance Labor Losses. Maintenance labor sitting idle during planned windows. If your wrench-time during scheduled work is 35%, then two-thirds of your maintenance labor is non-productive even on a good, planned day. 
    1. Scheduled Engineering Labor Losses. Engineering labor wasted during planned project windows, usually from scope creep, unclear handoffs, or late parts and drawings. Engineering hours are among the most expensive in the plant, so wasting them hits your project capital costs directly. 
    1. Scheduled Operations Labor Losses. Operations labor lost during planned operations windows. Ten people standing around for a 15-minute handoff briefing is a real, recurring loss, every shift, forever. 

    The six other human efficiency losses 

    1. Management and Planning Losses. Wait time caused by poor planning of the work itself: waiting for materials, tools, instructions, permits, or for equipment to be released. This is the single biggest source of lost wrench-time in maintenance, and it’s almost always a symptom of a reactive culture rather than lazy people. 
    1. Operating Motion Losses. Inefficiency in how operators have to move: bending, stretching, walking to fetch parts, hunting for tools. The hidden cost here isn’t just slower work; it’s injury risk. Every workers-comp incident is six figures of direct cost plus the productivity and morale damage around it. 
    1. Line Organization Losses. Inefficiency from how the line is laid out and how the workload is balanced across stations. It shows up as the same operators always being overloaded while others sit idle, or as bottlenecks nobody can quite explain. 
    1. Logistics Losses. Time lost moving material around the plant: operators walking for parts, dollies waiting on forklifts, work backing up because the next station can’t accept it. A finished pallet that sits 20 minutes waiting for a forklift is 20 minutes of unnecessary tied-up product, plus a safety hazard. 
    1. Waiting Losses. Operators waiting on equipment, materials, instructions, or each other. Easy to spot, hard to act on. This is one of the most demoralizing losses there is, because idle time tells your people that nobody values their time. 
    1. Setup and Adjustment Labor Losses. The labor side of equipment setup and adjustment, where skilled people are tied up redoing work that should have been right the first time. It’s a doubled cost: the equipment is down, and high-skill labor is being burned on something that was preventable. 

    Real-world example: wrench-time on a reactive shift. A maintenance supervisor films a typical shift. Out of eight paid hours per technician: 

    • Actual wrench time on equipment: 2.1 hours. 
    • Walking to and from the parts crib: 1.4 hours. 
    • Looking for tools: 0.9 hours. 
    • Waiting for permits or for production to release equipment: 1.1 hours. 
    • Waiting for instructions or supervisor decisions: 0.6 hours. 
    • Breaks, meetings, and paperwork: 1.9 hours. 

    Wrench-time comes out to 26%. With proper planning and kitting, world-class crews hit 55% to 60%. Closing that gap means doing roughly twice the work with the same headcount. That, in one shift, is a Management and Planning Loss you can see and size. 

    Wrench-time is the canary 

    If you want one number that tells you whether your plant has a human efficiency problem, it’s wrench-time: the share of paid maintenance hours actually spent turning wrenches on equipment. A reactive plant runs around 25% to 35%. A well-planned plant runs 55% to 65%. That gap isn’t about working harder. It’s about whether the work was set up so people could do it. 

    Try it yourself 

    Pick one of these to put a rough dollar value on this week: 

    • Time spent waiting for parts across your last five work orders. 
    • Distance an operator walks on your busiest line in a single shift, roughly estimated. 
    • The number of times someone had to stop and ask a supervisor for a decision before they could keep working. 

    Each of these is a number, and each number has a cost. Try to attach one. 

    Key takeaways 

    • Human efficiency losses mirror the equipment losses, but the fix is planning, organization, and training, not maintenance. 
    • Wrench-time is the canary: a reactive plant runs 25% to 35%, a planned plant 55% to 65%. 
    • Operating motion and line organization losses are large but invisible. They surface as fatigue, injuries, and bottlenecks. 
    • Waiting losses crush morale. Fix them and engagement rises right alongside productivity. 


    Coming next, Part 2, Post 4: The 10 Resource Losses.

    If you want to understand where your labor hours are slipping away, start with one number this week. Measure it. Put a dollar value on it. When you can see the loss, you can recover it. If you want help quantifying these losses inside your plant, reach out and we will walk you through the first assessment.

  • Business Acumen: The 11 Equipment Losses

    Business Acumen: The 11 Equipment Losses

    The 11 Equipment Losses 

    The machines are talking. Most plants only hear the loudest one. 

    In the last post we named the three families of loss. Now we go into the first and most familiar one: the 11 ways your equipment quietly hands money back. Familiar is the trap here. Most plants chase the loud, visible losses and walk right past the bigger, quieter ones. By the end of this post you’ll know all eleven by name, and you’ll know which ones are probably costing you the most. 

    The 11 equipment losses split into two groups: four are scheduled, and seven are unplanned. Both cost money. The scheduled ones are necessary, but necessary is not the same as efficient. 

    The four scheduled losses 

    These are the planned reasons you take a line down. You can’t eliminate them, but you can absolutely tighten them. 

    1. Scheduled Maintenance Time. Planned downtime for PMs, lubrication routes, inspections, and calibrations. The loss isn’t the PM; it’s the slop around it. A four-hour PM that runs six because parts weren’t staged just bled you two hours for nothing. 
    1. Scheduled Engineering Time. Planned downtime for installs, upgrades, and line modifications. A poorly scoped install that creeps from two days to five delays your return to production and burns labor the whole time. 
    1. Scheduled Operations Time. Planned downtime for inventory counts, training, cleanings, and audits. Stretching a two-hour training into a lost six-hour shift because nothing else was organized around it is pure waste. 
    1. Lack of Demand. The line isn’t scheduled because there are no orders. That’s not the plant’s fault, but the fixed-cost meter still runs during idle hours. Using that time well, for extra PMs, training, or projects, is the plant’s opportunity. 

    Real-world example: the PM that ran long. A four-hour planned PM on a packaging line took seven hours. The wrong gasket was kitted, costing 30 minutes to source the right one. Two technicians showed up without the right calibration tool, costing 45 minutes. Startup defects after restart threw away 90 minutes of product. The PM itself was fine. The planning around it was not. That extra three hours cost about $9,000 in lost contribution, and a 30-minute pre-PM kitting check would have prevented most of it. 

    The seven big losses 

    These are the seven unplanned losses you have the most control over, and they’re the ones that move OEE the most. This is where most reliability programs focus, and rightly so. 

    1. Setup and Adjustments. Deviation from a set standard of time. For example, a scheduled 30-minute changeover takes 45 minutes. The 15 minutes that was unplanned cost you units, equating to profit lost.  
    1. Breakdowns. Unplanned stops of 10 minutes or more that need a part to fix. This is the most visible loss, which is exactly why it gets too much of the attention. A single major breakdown can wipe out a week of contribution margin on a critical line. 
    1. Process Failures. Unplanned stops of 10 minutes or more that do not need a part: sensor faults, software glitches, control logic, operator confusion. These get missed because they don’t look like classic breakdowns, but they burn just as much time and often force a quality check on whatever ran before the stop. 
    1. Speed Losses. The gap between design speed and actual run speed. This is the most insidious loss in the building. A line built for 100 units a minute that runs at 80 has lost 20% of its capacity, and not one minute of it shows up on a downtime sheet. 
    1. Minor Stops. Stops under 10 minutes. Death by a thousand cuts. Two hundred short stops of three minutes each add up to 10 hours of downtime a week, invisible on the dashboard because no single event is big enough to notice. 
    1. Startup Defects. Defective product made during warm-up after a stop or changeover. Most plants accept this as “just how it is.” It isn’t. Reducing startup waste is one of the highest-return quality plays available. 
    1. In-Process Defects. Defective product made during normal running. This is a direct hit to material and labor cost, because a defective unit carries the full cost of being produced and generates exactly zero revenue. 

    Real-world example: the minor stops nobody sees. On a frozen-meal packaging line, the operator hits reset about 100 times a shift to clear minor jams from a tray feeder. Each reset takes 90 seconds. That’s 150 minutes per shift, two and a half hours of downtime, every shift, never logged because each event is under 10 minutes. At $4,200 an hour in lost contribution, that’s $10,500 per shift, or about $7.5M a year across three shifts. The fix was a $14,000 redesign of the tray-feed transfer. Payback: less than one day. 

    Read those two examples back-to-back and you can see the lesson. The loud loss, the breakdown, gets a war room. The quiet loss, 90 seconds at a time, gets a $7.5M annual bill and no attention at all. 

    Try it yourself 

    Walk one of your lines for 30 minutes during normal running. Tally three things: 

    • Every time the line stops or hesitates. 
    • Whether each stop was over or under 10 minutes. 
    • Whether anyone wrote it down. 

    Then ask how much of what you just watched is actually making it into your reported OEE. The gap between what you saw and what got recorded is your minor-stops opportunity, and it’s usually a lot bigger than anyone expects. 

    Key takeaways 

    • Equipment losses split into 4 scheduled and 7 unplanned. The 7 unplanned are the ones that move OEE. 
    • Speed losses and minor stops are the most under-counted, and often the largest. 
    • Most plants over-focus on breakdowns because they’re visible. The bigger money usually hides in minor stops, speed, and quality losses. 
    • If you can’t tell a Process Failure from a Breakdown, you can’t match the right strategy to the loss. 


    Coming next, Part 2, Post 3: The 9 Human Efficiency Losses. 

  • Business Acumen: Where the Money Hides

    Business Acumen: Where the Money Hides

    Where the Money Hides 

    Profit is not won by big swings. It’s won by spotting the leaks that drain it every day. 

    The 30 Losses Framework 

    Walk into your plant tomorrow and ask one question: “Where are we losing money?” You’ll get a different answer from every department. Operations will say breakdowns. Maintenance will say bad operating practices. Engineering will say poor design. Finance will say overspending. 

    Here’s the thing. They’re all right. They’re each describing one part of the same elephant. What they’re missing is a single map that names every part at once, so the plant can stop arguing about whose answer is correct and start working the whole animal. 

    That map is the 30 Losses framework. 

    The idea, in plain English 

    The 30 Major Losses are the 30 buckets where time, effort, and material slip away in a manufacturing facility. If you know which bucket your loss is in, you know where to go to get it back. 

    That’s the whole value of naming things. A vague sense that “we’re leaving money on the table” funds nothing. “We have a speed loss bucket worth $40,000 a month on Line 3” funds a project. The framework turns a feeling into a target. 

    Three families of loss 

    The 30 losses sort into three families: 

    • 11 Equipment Losses. Time and capacity lost on the machines themselves. 
    • 9 Human Efficiency Losses. Time and effort lost in how people work. 
    • 10 Resource Losses. Money lost in materials, energy, and inventory. 

    This split does real work for you. Together these categories tell you whether your problem is a machine problem, a people problem, or a resource problem; and that distinction decides where you should spend your improvement dollars. Pouring maintenance budget at what is actually a materials problem is how plants stay busy and broke at the same time. 

    How the losses stack up 

    Picture a waterfall. You start at the top with all the hours theoretically available to a machine, 168 hours in a week, and you chip away. 

    • First you subtract scheduled downtime, the time you planned not to run. 
    • Then you subtract the unplanned losses, the breakdowns and stops. 
    • Then you subtract speed losses, the gap between design pace and actual pace. 
    • Then you subtract quality losses, the output you made but couldn’t sell. 

    Whatever survives at the bottom is your real productive output. The same waterfall logic applies to people and to resources. Every loss bucket is just a place where water leaks out on the way down. 

    The three roll-ups that score it 

    Three terms summarize how badly the 30 losses are bleeding you. We’ll calculate each one in Part 3; for now, just learn what they mean. 

    Metric  What it measures  Goal 
    Loading  How much of available time you scheduled to run  High enough to meet demand without burning out the plant 
    OEE (Overall Equipment Effectiveness)  Of the time you scheduled, how productive the equipment actually was  World-class is about 85%. Most plants live around 40% to 60%. 
    TEEP (Total Effective Equipment Performance)  Of all available time, 24 hours a day, every day, what did you actually produce?  Reveals the true ceiling. Big TEEP gaps mean big hidden capacity. 

    Why “hidden factory” is the phrase that matters 

    Here’s the line that should change how you see your plant. If your TEEP is 30%, you have a second factory hidden inside your factory. 

    You’re already paying for the building. You’re paying the depreciation on the equipment. You’re paying most of the labor. That capacity exists; it’s just buried under the 30 losses. And recovering it is almost always far cheaper than building a new line. The 30 losses are the map to that hidden factory, and a typical plant is sitting on a hidden factory worth 30% to 50% of its current capacity. 

    That’s not a rounding error. That’s a second plant you already own. 

    Try it yourself 

    Before the next post, do a back-of-the-envelope estimate for one critical line: 

    • Roughly what percentage of scheduled time does it actually run well? That’s a rough feel for OEE. 
    • Now factor in all the hours it isn’t even scheduled. That gets you toward TEEP. 

    You don’t need precision yet. You’re just trying to feel the size of the gap between what you produce and what you could. That gap is the rest of Part 2. 

    Key takeaways 

    • 30 losses, three families: Equipment (11), Human Efficiency (9), Resources (10). 
    • Loading shows how much you tried; OEE shows how well the equipment ran; TEEP shows the full opportunity. 
    • A typical plant has a hidden factory worth 30% to 50% of its capacity sitting inside its current walls. 
    • You can’t fix what you can’t name. Naming the loss is the first job, and it’s what this part of the series is for. 


    Coming next, Part 2, Post 2: The 11 Equipment Losses. 

  • Business Acumen: Profit vs. Cash, Why They Are Not the Same

    Business Acumen: Profit vs. Cash, Why They Are Not the Same

     Profit vs. Cash, Why They Are Not the Same 

    This is the post most operators and maintainers would skip. Don’t. The day you understand the difference between profit and cash is the day your business cases start getting approved faster. 

    We’ve covered how the business makes money and how to read its three statements. Now comes the idea that quietly decides whether your projects live or die, and almost nobody on the floor is taught it. 

    Profit and cash are not the same thing. They feel like they should be. They are not. Understanding why is one of the most valuable things you can carry into a budget meeting. 

    The simple distinction 

    In plain English. Profit is an accounting concept. It’s what the books say after revenue and expenses are matched up, even if the cash hasn’t actually moved. 

    Cash is the green stuff in the bank. You either have it or you don’t. 

    Here’s the uncomfortable part: a company can post a profit on paper while running out of cash, and a company can be sitting on plenty of cash while losing money. The two numbers tell different stories, and you need to be fluent in both. 

    How they drift apart 

    There are a handful of everyday situations that pull profit and cash in different directions. You’ll recognize all of them. 

    • Inventory builds up. You spent cash buying raw material and converting it, but it’s sitting as work in process or finished goods. That cost parks on the balance sheet as inventory, not in COGS; so profit looks fine, but the cash is gone. 
    • Customers pay slowly. You shipped the product and recorded the revenue and profit, but the cash won’t land for 60 days. Meanwhile, payroll is due Friday. 
    • Big capital projects. You wrote a $2M check for a new line, but only a slice of it gets depreciated this year. Cash is way down; profit barely moved. 
    • Spare parts hoarding. You bought $300K of insurance spares because everyone insisted “we have to have these.” Profit is unchanged. The cash is gone. 

    Why plant leaders should care 

    This isn’t trivia for the finance team. It’s directly about whether your work gets funded. Three reasons: 

    • Capital approvals depend on cash. If the company is cash-tight, your $500K reliability project can get deferred even when the ROI is excellent. The “no” you heard wasn’t about value. It was about cash. 
    • Inventory decisions are cash decisions. Every reduction in excess work in process or dead MRO is cash handed back to the company. That’s a win you can deliver without selling a single extra unit. 
    • “Save money” sometimes means “free up cash,” not “cut expense.” Knowing which one you’re offering changes how you frame the pitch, and changes who says yes. 

    A story your CFO will love 

    Real-world example: the MRO stockroom cleanup. A plant audits its spare-parts stockroom and finds: 

    • $1.2M of MRO inventory on the books. 
    • $340K of it hasn’t moved in five or more years; obsolete or duplicates. 
    • $180K is for equipment no longer even in service. 

    They sell or write off the obsolete parts and tighten the min and max levels on the rest. The result is about $400K of cash returned to the company. The income statement barely flinches, because write-offs actually sting profit in the short term, but the balance sheet and cash position improve in a big way. 

    That is a story the CFO loves, and notice why: it hurt profit slightly while freeing real cash. If you only spoke the language of profit, you’d never pitch it. Because you understand cash, you can. 

    Try it yourself 

    Walk your stockroom, or pull the MRO inventory report. Then: 

    • Find three line items that look like they haven’t moved in years. 
    • Estimate the dollar value sitting on the shelf. 
    • Ask two questions: do we still own the equipment those parts support, and are they still needed? 

    This is a five-minute exercise that routinely surfaces five- and six-figure cash opportunities hiding in plain sight. 

    Key takeaways 

    • Profit and cash are not the same, and a plant leader needs to be fluent in both. 
    • Inventory ties up cash without touching profit until it moves. 
    • Spare parts strategy is a cash strategy. 
    • When a project gets deferred, it’s often a cash issue, not a value issue. Frame it accordingly. 

    Wrapping up Part 1 

    You now have the foundation: how the business makes money, how to read its statements, and why cash and profit tell different stories. That’s “thinking like the business.” From here on, you can look at anything on your floor and ask the only questions that get things funded. What is this doing to cost, to cash, and to risk? 

    Next, we put that lens to work and go hunting. There’s far more money leaking out of your plant than anyone is tracking, and most of it is hiding in places nobody thinks to look. 


    Coming next, Part 2: Where the Money Hides.

  • Business Acumen: Financial Statements for Operators

    Business Acumen: Financial Statements for Operators

    Financial Statements for Operators 

    You don’t need to read them like an accountant. You need to read them like the person who moves the numbers on them. 

    Say the words “financial statements” in a plant and watch people’s eyes glaze over. Don’t let yours. Here’s the good news: there are only three, and you only need a working understanding of each. Together they answer three plain questions. Is the company healthy? Is it growing? Can it pay its bills? 

    Once you can read these three the way you read a downtime report, the budget conversation stops being intimidating and starts being a place where you have the upper hand. 

    The three statements at a glance 

    Statement  What it tells you  Plant floor translation 
    Income Statement  Did we make a profit over a period of time?  Did we ship more value than we burned in costs? 
    Balance Sheet  What do we own and what do we owe right now?  How much inventory and equipment is sitting around? 
    Cash Flow Statement  Did cash actually come in or go out?  Can we pay vendors, payroll, and capital projects this month? 

    The income statement (the P&L) 

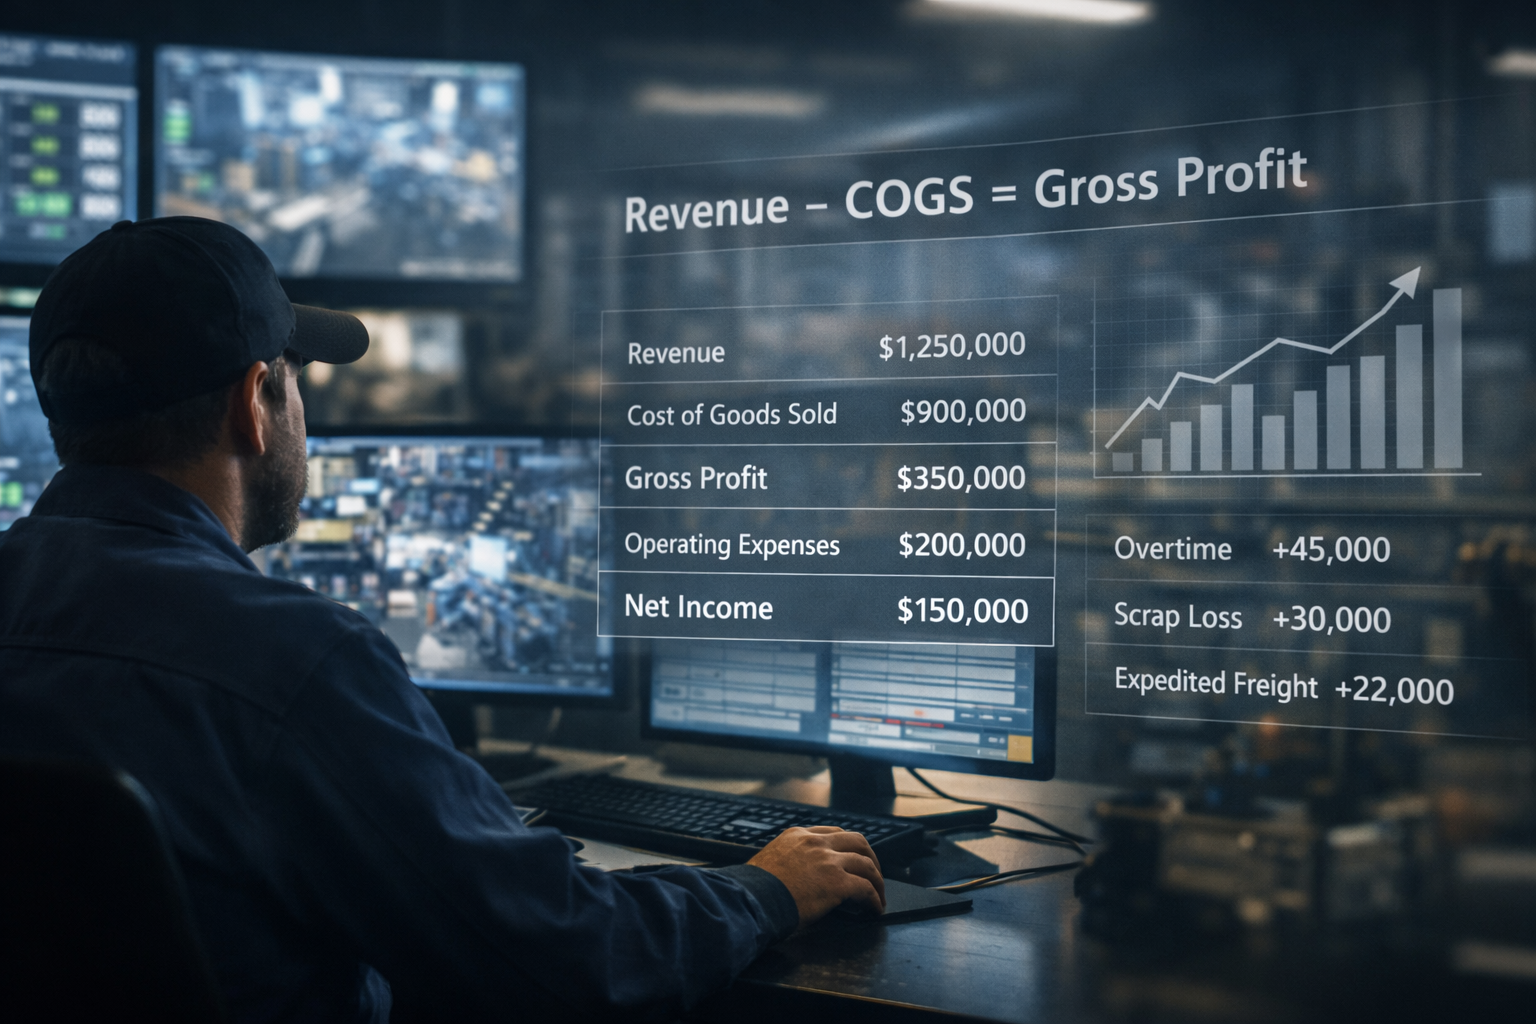
    Read it top to bottom and it tells a story: 

    • Revenue. What we sold. 
    • Minus Cost of Goods Sold (COGS). What it cost to make what we sold: materials, direct labor, manufacturing overhead. 
    • Equals Gross Profit. 
    • Minus Operating Expenses. Sales, general and administrative, R&D, other overhead. 
    • Equals Operating Income (EBITDA). 
    • Minus Interest, Taxes Depreciation and Amortization. 
    • Equals Net Income. 

    Here’s the part that should make you sit up. Almost everything that happens on your floor lands in one line: COGS. Scrap, rework, breakdown overtime, energy, raw material; all of it flows into Cost of Goods Sold. That is why plant performance is one of the most direct ways to move profit in the entire company. You are not a support function on this statement. You are sitting on the biggest lever it has. 

    Real-world example: how one bad week shows up. A bottling plant strings together breakdowns in week 3 of the month. Watch where it lands on the income statement: 

    • Volume drops, so revenue falls about $180,000. 
    • Overtime to catch up pushes COGS labor up $22,000. 
    • Expedited freight to hit customer dates adds $15,000 to COGS freight. 
    • Scrap from startup defects after each restart adds $9,000 in COGS materials. 

    Total profit hit: roughly $226,000 in one week, and most of it stayed invisible until the month closed. 

    That last line is the whole point. The damage was real on the floor in week 3, but nobody felt it on paper until the books closed weeks later. The person with business acumen connects those two moments before the month ends. 

    The balance sheet 

    If the income statement is a movie of a time period, the balance sheet is a photograph taken on a single day. It shows everything the company owns and everything it owes. 

    Assets = Liabilities + Equity 

    What we have = what we owe + what’s left for the owners. 

    Where does the plant show up here? 

    • Inventory. Raw materials, work in process, and finished goods. Every dollar tied up here is a dollar not earning anything else. 
    • Property, Plant and Equipment. Your machines, lines, and building. Their value is depreciated over time. 
    • Spare parts (MRO). Sometimes counted as inventory, sometimes capitalized. Either way, it’s cash sitting on a shelf. 
    • Accounts Payable. What you owe vendors for materials and services you haven’t paid for yet. 

    Notice the tension built into your stockroom. Carry too much “just in case” spare-parts inventory and you tie up cash that could be working elsewhere. Carry too little and you risk extended downtime when a critical part isn’t on hand. There’s no perfect number; there’s a strategy, and we’ll build it in Part 5. 

    The cash flow statement 

    This is the one that trips people up, so I’ll keep it short here and give it the full treatment in the next post. The headline is this: a company can be profitable and still go broke, because profit and cash are not the same thing. The cash flow statement tracks the actual money moving in and out of the bank account, in three buckets: 

    • Operating cash flow. Cash from running the business. 
    • Investing cash flow. Cash spent on, or received from, buying and selling assets like equipment. 
    • Financing cash flow. Cash from loans, investors, dividends, and debt repayment. 

    Hold that thought. The gap between profit and cash is where a lot of good plant decisions live or die, and it’s exactly where we’re headed next. 

    Try it yourself 

    Pull your plant’s last income statement or ask Finance for one. Find: 

    • Total revenue for the period. 
    • COGS. 
    • Gross profit (revenue minus COGS). 
    • Gross margin percentage (gross profit divided by revenue). 

    Then estimate one thing: what happens to gross margin if your plant cuts unplanned downtime by 5%? Even a rough number is fine. The point isn’t precision yet; it’s building the muscle of connecting a floor action to a financial line. 

    Key takeaways 

    • There are only three statements, and you only need a working grasp of each. 
    • Income Statement is the profit story, and COGS is where your floor lands. 
    • Balance Sheet is what you own and owe; inventory, equipment, and spare parts are your footprint on it. 
    • Cash Flow is actual money movement, and profit and cash are not the same thing. 
    • Plant performance moves COGS directly, and COGS moves net income directly. You hold a real lever. 


    Coming next, Part 1, Post 3: Profit vs. Cash, Why They Are Not the Same.

  • Business Acumen: Thinking Like The Business

    Business Acumen: Thinking Like The Business

    How Your Business Actually Makes Money 

    Before you can fix the floor, you have to see the floor the way the business sees it. 

    Most of us came up through the technical side. We learned the equipment, the process, the schedule. What almost nobody handed us along the way was a simple picture of how the whole company actually makes money. And until you have that picture, every financial conversation feels like it’s happening in a language you were never taught. 

    So let’s start there. Forget the org chart for a minute. No matter how complicated your company looks on paper, it runs on the same simple engine. 

    The engine, in plain English 

    A manufacturing business makes money by converting raw materials into finished goods that customers will pay more for than the materials and the conversion cost combined. 

    That difference is your contribution. You pay your fixed costs out of that contribution, and whatever is left is profit. That’s the whole machine. Everything else in this series is just a more detailed look at one part of it. 

    Three ideas make the engine run: how revenue is built, how costs behave, and what’s left over. Let’s take them in order. 

    The three levers of revenue 

    Revenue doesn’t just show up. It gets built from three knobs, and plant decisions touch all three. 

    • Volume. How many units you ship. 
    • Price. What you charge per unit. 
    • Mix. Which products you ship, because some carry higher margins than others. 

    These interact in ways that aren’t always obvious. Push volume by discounting to move product, and your price knob drops; you might end up flat. Ship more of your high-margin products, and revenue can climb even if total units stay the same. When you free up capacity on a constrained line, you’re not just making “more stuff.” You may be changing the mix, and that can matter more than the raw count. 

    How costs behave: fixed versus variable 

    This is the single most important cost concept on the floor, and it’s the one that explains why downtime hurts the way it does. 

    Cost type  Behavior  Plant examples 
    Fixed  Stays the same whether you make 1 unit or 1,000  Building lease, salaried staff, depreciation on equipment 
    Variable  Rises and falls with how much you produce  Raw materials, packaging, energy on running equipment, hourly overtime 

    Here’s why it matters. When a line goes down, you stop spending the variable cost on the units you didn’t make, except for the labor you are paying to stand around. This raises the cost per unit and the fixed cost meter keeps running the entire time the line sits dark. The lease, the salaries, the depreciation; none of it pauses. That’s why every hour of unplanned downtime costs more than people expect. 

    Contribution margin: the number that sizes everything 

    Contribution margin is the money left from each unit sold after you subtract that unit’s variable cost. It’s what’s available to cover fixed costs and other overhead and then turn into profit. 

    Contribution margin per unit = selling price minus variable cost per unit 

    Total contribution = contribution per unit times units sold 

    Remember the packaging line from the intro? Let’s do the full math this time. 

    Worked example: a pet food packaging line. A 30 lb bag sells for $24. The variable cost (kibble, bag, film, energy, direct labor) is $14. So contribution per bag is $10. 

    Plant fixed costs are $400,000 per month. Divide that by the $10 per bag, and your break-even is 40,000 bags per month. Every bag past 40,000 drops a clean $10 to the bottom line. 

    Now a breakdown costs you 5,000 bags this month. If you were already above break-even, your fixed costs were covered, so that $10 per bag was pure profit. Five thousand bags times $10 is $50,000 of profit gone. Not revenue. Profit. And you’ll never get it back. 

    That’s the move that gets your projects funded. Anyone can say “the line was down for a shift.” The person with business acumen says “that shift cost us $50,000 in profit,” and suddenly the room is paying attention. 

    Break-even thinking 

    Break-even units = fixed costs divided by contribution margin per unit 

    Once you know your break-even point, the picture gets sharp. Every unit above it is profit. Every unit below it is a loss. This is also why a plant running close to break-even feels every disruption so hard; there’s no cushion of profitable volume to absorb the hit. The closer you operate to that line, the more expensive each lost unit becomes. 

    Try it yourself 

    Pick one product line in your plant. Estimate these, or ask Finance: 

    • Selling price per unit. 
    • Variable cost per unit. 
    • Total monthly fixed cost allocated to that line. 

    Then calculate: 

    • Contribution margin per unit (price minus variable cost). 
    • Break-even units per month (fixed cost divided by contribution margin). 
    • How many units above break-even you shipped last month. That’s your profit contribution. 

    If you don’t know these numbers, that’s not a failure. That’s the first finding of the exercise, and it’s exactly the gap this series is here to close. 

    Key takeaways 

    • Revenue is moved by volume, price, and mix, and plant decisions touch all three. 
    • Fixed costs run no matter what you produce. That’s why downtime is so expensive. 
    • Contribution margin is the single most important number for sizing the impact of a loss. 
    • Every unit above break-even is profit. Every unit below it is bleeding.

    Coming next, Part 1, Post 2: Financial Statements for Operators. 


  • Business Acumen for Manufacturers

    Business Acumen for Manufacturers

    The gap nobody warns you about, and the series that closes it 

    In all my years of turning plants from reactive to profit-producing, I’ve found a handful of gaps that show up again and again, and they don’t seem to care what industry you’re in. Food, chemicals, metals, packaging, pulp and paper; the same gaps are waiting in every plant I walk into. 

    The biggest one is leadership constraint. That’s a series for another day. 

    The close second is business acumen, and it’s the one almost nobody sees coming. It’s hidden. Most people don’t know it exists, let alone know they need it. They were promoted because they were good at the technical work. They could fix the line, run the schedule, hit the numbers. Then one day someone in a meeting asked, “Okay, but what does that do to EBITDA?” and the room went quiet. 

    If you’ve ever been in that room, this series is for you. 

    What business acumen actually is 

    Let’s clear something up right away: business acumen is not an accounting class. You don’t need a finance degree, and you don’t need to love spreadsheets. 

    Business acumen is the ability to look at what’s happening on your floor and understand what it’s doing to cost, cash, and risk, and then make decisions accordingly. It’s the bridge between a leaking gearbox and a board meeting. It’s what lets you walk into a budget conversation and say, in language leadership actually funds, “This failure mode is costing us $50,000 a month in lost profit, and here’s the fix that pays for itself in eleven weeks.” 

    That’s the difference between being the person who asks for money and being the person who makes the case for it. 

    Here’s the part that surprises people most: you already have the data. The downtime logs, the work orders, the scrap reports, the parts usage; it’s all sitting in your systems right now. What’s missing isn’t data. What’s missing is the skill to translate that data into the three things every business actually cares about: cost, cash, and risk. 

    That skill is learnable. That’s what this series is about. 

    Why this gap is so expensive 

    When a line goes down, most people instinctively think about lost revenue. But revenue isn’t what disappears. Profit is. 

    Picture a packaging line. A bag of product sells for $24, and the variable cost to make it (materials, film, energy, direct labor) is $14. That leaves $10 of contribution on every bag. Now a breakdown costs you 5,000 bags this month. That’s not $120,000 of revenue gone, and it’s not even the $50,000 of contribution you’d guess at first glance. Once you account for the fixed costs that kept running the whole time the line sat dark, the hit to the bottom line is real money you’ll never get back. 

    The technician who can see that math, and explain it, gets their projects funded. The one who can’t gets told “no budget this quarter” and watches the failure repeat. 

    That’s the cost of the acumen gap. It’s not abstract. It shows up in every deferred repair, every under-resourced reliability program, and every good idea that died because it was pitched in the wrong language. 

    How this series is built 

    We’re going to break business acumen into six parts, with multiple posts under each. We’ll go in order, because the parts build on each other; but each post will stand on its own so you can jump to what you need. 

    Part 1: Thinking Like the Business. Before you can fix the floor, you have to see the floor the way the business sees it. How your company actually makes money, the financial statements that matter, and why profit and cash are not the same thing. 

    Part 2: Where the Money Hides. Money leaks out of a plant in far more places than most people track. We’ll map out exactly where it’s hiding, across equipment, people, and resources, so you stop guessing and start finding it. 

    Part 3: Measuring What Matters. You can’t fund what you can’t size. This is where you learn to measure the bleeding, to put a real number on a loss instead of a gut feeling, and where to focus first. 

    Part 4: Building the Business Case. This is the financial language that gets things funded: cost-benefit analysis, payback, ROI, and the silent killer almost nobody quantifies, the cost of inaction. 

    Part 5: Connecting Reliability to Profit. Here’s where it all comes together at the strategic level: throughput thinking, working capital and spare parts, and how maintenance stops being a cost center and starts being a profit lever. 

    Part 6: Acumen in Action. The capstone. Making decisions and tradeoffs under real constraints, translating technical findings into business language, and putting the whole picture to work in your next staff meeting. 

    A promise before we start 

    Every formula and idea in this series has been kept as simple as it can be while still being honest. If a CFO would scoff at it, it’s not here. If a frontline supervisor wouldn’t understand it, it got rewritten. 

    Simplicity is not the enemy of rigor. It’s the price of being heard. 

    If you can talk about cost, cash, and risk in the same sentence as your equipment, you’re already doing it right. By the end of this series, that won’t feel like a stretch. It’ll feel like how you think. 

    Let’s get to work. 

    Coming next, Part 1, Post 1: How Your Business Actually Makes Money. 

  • The High Cost of Lean at the Wrong Maturity Level

    The High Cost of Lean at the Wrong Maturity Level

    Walk into almost any plant with an active continuous improvement program and you will find a portfolio of lean tools in deployment. Value stream mapping, kaizen events, SMED, 5S, standard work, visual management, and sometimes a kanban system or a set of Six Sigma DMAIC projects layered on top. The CI manager has a roadmap, the lean coordinator has a calendar full of events, and the team is busy.

    Busy is not the same as effective.

    There is a quiet failure mode in continuous improvement programs that appears in many organizations. Lean tools are often deployed at a moment when the operation is not mature enough to benefit from them. The tools themselves are not incorrect, and they are frequently executed with technical precision. When they are applied before the underlying operation is doing the right things, the result is a system that performs the wrong activities with greater speed and consistency.

    This article focuses on that sequencing challenge and explains why effectiveness must always precede efficiency in every operation.

    What Lean Is Actually For

    Lean is fundamentally the systematic removal of waste. This principle shaped the Toyota Production System, reflected the direction Henry Ford was already pursuing a generation earlier, and remains the foundation of every legitimate lean tool in use today.

    The eight wastes that practitioners recite so often are simply variations of the same idea. Organizations must identify activity that does not add value to the customer, remove it, streamline what remains, and continue that cycle with discipline.

    When lean is applied at the correct moment, it becomes transformational. It elevates mature operations into truly excellent ones, reveals capacity that was previously hidden inside the friction of daily work, and removes real cost from the business.

    When lean is applied at the wrong moment, it produces a very different outcome.

    The Failure Mode: Efficient Wrong Things

    A process that does not deliver the correct outcome can be mapped, streamlined, standardized, balanced, and improved through a series of lean events. Cycle time will fall, variation will tighten, and the team will celebrate the visible gains. The underlying operation, however, will not be meaningfully better.

    A classic example is a maintenance organization that operates reactively. Work orders arrive unplanned, parts are expedited, jobs are rushed, equipment fails again, and the cycle repeats. A lean team may map the value stream of this reactive work and remove waste from the process. Technicians will reach broken equipment faster, parts will be staged more effectively, and the workflow will appear more organized.

    The organization will now have a highly efficient reactive maintenance function, which is still a reactive maintenance function. The losses being optimized were never meant to be optimized. They were meant to be eliminated through a shift to proactive maintenance. Lean has made the organization better at the wrong thing.

    This pattern appears in every domain. A quality team that relies on end‑of‑line inspection can make the inspection process more efficient, although the correct move is to improve the upstream process so inspection becomes unnecessary. A planning function that spends most of its time expediting can streamline the expediting process, although the correct move is to plan further ahead so expediting is no longer the dominant mode. An operations team that performs constant changeovers due to poor scheduling can reduce changeover time through SMED, although the correct move is to consolidate the schedule.

    In each case, lean produces measurable results, yet the fundamental issue remains untouched. In some organizations, early lean deployment even reinforces the wrong process by making it appear optimized and acceptable.

    The Curve You Are Trying to Climb

    Improvement does not follow a straight line. It follows a curve.

    When an operation is underperforming because it is doing the wrong things, missing essential disciplines, or lacking mature core processes, the improvement potential from becoming effective is enormous. A reactive plant that becomes proactive experiences significant gains. A plant with no planning function that builds one experiences significant gains. A plant with no precision standards that adopts them experiences significant gains. These are the high‑leverage moves that come from improving effectiveness.

    Eventually, the major effectiveness gains are exhausted. The plant begins doing the right things consistently. The remaining losses are smaller, more subtle, and more deeply embedded in the flow of work. This is the point where the curve flattens, and efficiency becomes the primary lever. Lean tools are designed for this stage, when the operation is mature and the remaining waste is difficult to detect.

    The mistake occurs when organizations reach for lean while they are still on the steep part of the effectiveness curve. They trade large, fundamental gains for small, incremental ones. They invest time, resources, and credibility into lean events that produce modest improvements while ignoring the foundational changes that would produce step‑change performance.

    Effectiveness must come first. Efficiency must follow. The order is not optional.

    How to Tell Which Phase You Are In

    If you are unsure whether your operation is ready for serious lean deployment, consider the following questions.

    Are you doing the right things, defined by current best practice in your industry? This is not a question about effort or activity. It is a question about whether the disciplines, methodologies, and processes that produce excellent outcomes are present and functioning.

    Have you closed the obvious gaps? Major discipline gaps such as the absence of a planning function, a predictive program, operator care, work execution standards, or asset criticality analysis are effectiveness issues. Lean will not fix them.

    Are your remaining losses small, difficult to identify, and challenging to eliminate? This is a signal that lean is appropriate. The operation has matured, the obvious moves are complete, and the remaining waste is buried in well‑functioning processes.

    Do improvements sustain over time? Sustainability is a prerequisite. If basic disciplines erode within months, lean improvements will erode as well. The foundation must be stable before efficiency tools can take hold.

    If the honest answer to the first three questions is no, the organization is not ready for lean as the primary improvement lever. The focus must shift to effectiveness, capability building, and closing foundational gaps. Lean remains in the toolkit, although it should not lead the strategy.

    If the answer to the first three questions is yes, lean becomes the correct next step. The major effectiveness gains are behind you, and the remaining waste requires the precision of lean methods.

    What This Means for Your CI Strategy

    Several practical implications follow from this understanding.

    Sequence effectiveness work before lean work. Plants that begin from a reactive or under‑disciplined state should focus their initial improvement portfolio on building the right capabilities rather than running lean events against immature processes.

    Do not confuse activity with progress. A full CI calendar is evidence of activity, not improvement. Outcomes matter more than events.

    Match the tool to the maturity of the operation. Capability‑building methodologies such as RCM, planning and scheduling, criticality analysis, operator care, predictive maintenance, and standard work development belong on the steep part of the curve. Lean and Six Sigma belong on the flatter part. Use them in that order.

    Audit your CI portfolio for misapplied tools. Evaluate each initiative and determine whether it makes the organization better at doing the right thing or more efficient at doing the wrong thing. The answer determines whether the project belongs.

    Build lean capability in advance of when you will need it. This is not an argument against lean. It is an argument for sequencing. Train your people, build the skill, and develop the toolkit so it is ready when the operation reaches the appropriate level of maturity.

    The Bottom Line

    Lean is one of the most powerful improvement disciplines ever created. It elevates mature operations into elite performers and removes real cost from well‑functioning businesses. The principles are sound, the tools are excellent, and the methodology has earned its reputation.

    Timing determines the outcome. A powerful tool deployed at the wrong moment delivers the wrong result. Lean applied before effectiveness creates efficient bad processes. Lean applied after effectiveness creates excellent ones.

    Start with effectiveness. Establish the right disciplines. Mature the operation. Then apply lean to what remains and watch it deliver exactly what it was designed to deliver.

    Right thing first. Right thing efficiently second. Always in that order.

    If your organization is ready to move from activity to real progress, contact us to discuss how we can help you build the right foundation and deploy the right tools at the right time. Contact us today! 

  • Building a Pull System: How Corporate Teams Without Direct Authority Drive Real Adoption

    Building a Pull System: How Corporate Teams Without Direct Authority Drive Real Adoption

    This is the third post in a series on corporate functional teams that operate with indirect influence over the operating sites. The centers of excellence, governance functions, and operational support teams that develop standards and best practices and rely on the sites to actually adopt them. 

    The first post diagnosed the failure pattern, compliance theater driven by a default push model. The second post argued that the most counterintuitive rule for these teams is your peer group is not your working group, and your real customer is site leadership rather than the SME you work with day-to-day. 

    This third post is the practical playbook. How do you actually build a pull system? What are the operating mechanisms that make it work? 

    The Pull Process Flow 

    Start with the core process. In a pull system, the sequence is fundamentally different from the standard top-down rollout. Here’s what it looks like in operation: 

    Step 1: Sites assess against business outcomes. Not against your standard, against the outcomes their site leadership is accountable for. Production. Safety. Quality. Cost. Risk exposure. Whatever the site’s actual scorecard is. 

    Step 2: Sites identify gaps. Where are they falling short of their outcome targets? Which gaps are biggest? Which are most consequential? 

    Step 3: Sites prioritize. Out of the universe of gaps, which ones are they actually committing to close in the next year? This is the site’s plan, not the corporate team’s. 

    Step 4: Sites engage corporate to close the gap. Now and only now does the corporate team enter the picture. The site says, “We’ve identified this gap. We need a process, a tool, a methodology, or a standard to help us close it. Do you have one? If yes, can we use it? If no, can we work together to develop one?” 

    Step 5: Corporate determines if standardization is appropriate. Not every gap requires a standard. Some are local issues with local solutions. Some require methodology that’s already documented. Some genuinely require a new corporate standard because the gap will recur across sites. 

    Step 6: If standardization is needed, develop with the community. This is where the corporate team’s value-add lives. They convene a community of excellence, corporate SMEs plus site representatives to develop or update the standard. The site that identified the gap is in the room. So are sites with related challenges. 

    Step 7: Sites implement to close their gap. Adoption isn’t an end in itself. The standard is a tool the site is using to close a gap they identified. Adoption follows naturally because the site needs the result. 

    Notice what’s different. The trigger isn’t “corporate has issued a standard, sites must adopt.” The trigger is “a site has a gap, and corporate has a resource that can help close it.” The standard exists in service of the site’s outcome, not the other way around. 

    Knowing What to Standardize and What Not To 

    One of the most underappreciated parts of this model is knowing what to standardize and what not to. Every gap identified by a site shouldn’t trigger a corporate standard. If your team is in the standards business and standards are your only deliverable, every problem starts to look like a standardization problem. 

    Develop a decision tree. The criteria typically include: 

    • Recurrence. Will this gap appear at multiple sites? If it’s idiosyncratic to one site’s local conditions, a standard is overkill. That site needs a custom solution. 
    • Risk. Does the gap relate to safety, regulatory compliance, or material business risk? If yes, standardization is more justifiable even at lower recurrence. 
    • Variability cost. Is there a meaningful cost to having different sites solve the same problem differently? Sometimes yes (interoperability, shared services, central reporting); sometimes no. 
    • Maturity. Is the best practice well enough understood to be codified? Premature standards lock in suboptimal approaches. 

    If the decision tree says “yes, standardize,” the corporate team and the community of excellence develop the document. If the answer is “no,” the corporate team can still be useful by sharing what other sites have done, connecting the site to peers solving similar problems, or providing guidance but a formal standard isn’t the deliverable. 

    This discipline saves the corporate team from generating standards that nobody needs. It positions them as a team that knows when not to standardize, which paradoxically increases the credibility of the standards they do produce. 

    The Governance Charter 

    A pull system requires a written agreement between the corporate team and the sites about how the relationship works. I call this a governance charter. It’s a negotiated document not a corporate-issued one that establishes: 

    • The corporate team’s purpose, scope, and standards-development process 
    • The site’s responsibilities in the relationship,  gap identification, plan development, engagement with the community of excellence 
    • The cadence of meetings and reviews 
    • The metrics that will be used to assess the relationship’s effectiveness 
    • The escalation path when commitments are missed on either side 

    The act of writing the charter is itself a forcing function. When you sit down with site leaders to negotiate this, you discover what they’re actually willing to commit to, what they expect from you, and where the misalignments are. The conversation alone is often more valuable than most adoption initiatives the team has ever launched. 

    The charter also makes the relationship symmetric. It’s not a list of demands on the sites; it’s a list of mutual commitments. That symmetry is what makes the pull system actually pull. 

    The Site-Led Governance Review Meeting 

    The single highest-leverage operating mechanism in a pull system is the site-led monthly governance review meeting. 

    Most corporate teams run their site interactions backward. The corporate team owns the agenda. The corporate team asks questions. The sites answer. The corporate team checks compliance. The meeting is, in effect, an audit by another name. 

    Flip it. 

    In a site-led review, the site presents. The agenda belongs to them. They walk the corporate team and the other sites through their progress against their own annual plan, gaps identified, actions taken, results achieved, challenges remaining. The corporate team’s role is to listen, ask clarifying questions, and provide reinforcement when sites are doing well. 

    Run one site per meeting on a rotating cadence. By the end of the year, every site has presented at least once, and most have presented several times. 

    Two dynamics emerge from this format: 

    Dynamic 1: Positive Competition. When one site presents impressive results, the other sites in the room notice. They start asking themselves and each other “How are they doing that?” The next site to present typically steps up its game. Over time, you create a friendly competitive culture across the network. That competitive energy is something a corporate team can never manufacture by issuing standards. It only emerges when sites are presenting to each other. 

    Dynamic 2: Visible Reinforcement. Every time a site presents, the corporate team has the opportunity to publicly recognize what’s working. Find reasons to commend them for the rigor of their analysis, for the courage to share an honest setback, for the engagement they brought to a recent community-of-excellence working group. Public reinforcement, repeated over time, reshapes behavior more powerfully than audit-and-escalate ever will. 

    The meeting is not a corporate-driven status update. It’s a peer-to-peer learning forum the corporate team facilitates. 

    The One-Issue-Per-Site Discipline 

    Here’s a tactical mechanism that turns the pull system from a quarterly cadence into a continuous relationship: at any given time, every site should have at least one open issue that the corporate team is helping them solve. 

    Whatever the issue is a standard being developed, a gap analysis underway, a tool being piloted, a methodology being adapted, the site has corporate engagement on something they actually want help with. When that issue is resolved, the site brings forward another. The relationship is always live. 

    This serves two purposes. 

    First, it keeps the corporate team in problem-solving mode, which is the rebrand the entire pull system depends on. As long as you’re working real problems for real sites, you’re useful — which is the only thing that earns you the right to issue standards in the first place. 

    Second, it gives the corporate team a clean metric to report up the management chain: how many sites are actively engaged with our team on an issue right now? Of those engagements, how many resulted in measurable progress? That metric is far more meaningful than “standards issued” or “audits completed.” It tells you whether the team is actually being pulled in by the sites which is the entire goal. 

    If a site has no open issues with your team, that’s a signal. Either they don’t have any active gaps in your domain (rare), or they’re not engaging with you (more likely). Either way, it’s worth a conversation with site leadership about why. Frame it carefully: most sites complain that they don’t have enough resources to deliver on corporate expectations. The metric of “are sites taking advantage of the resources available to them?” turns that complaint back on itself. If there’s a corporate resource available and the site isn’t using it, that’s a different conversation than “we’re under-resourced.” 

    Measuring What Matters 

    The measurement shift is one of the hardest changes for corporate teams to make. Most teams measure activity: 

    • Standards issued 
    • Plans submitted 
    • Audits completed 
    • Findings closed 
    • Meetings held 

    These metrics tell you whether the corporate team is busy. They tell you nothing about whether the sites are getting better. 

    In a pull system, you measure two things: outcomes and behaviors. 

    Outcome metrics track whether the sites are actually improving in your domain. If your team is responsible for reliability, you measure unplanned downtime, mean time between failures, PM compliance trends. If it’s quality, defect rates and SOP adherence. If it’s safety, recordables, near-misses, and procedural compliance. The corporate team’s effectiveness is judged by whether the sites collectively are getting better, not by whether the team is busy. 

    Behavior metrics track whether the relationship is functioning as a pull system: 

    • How many sites engaged the team for help in the last quarter? 
    • How many open issues are the team currently working with sites? 
    • How active is site participation in the community of excellence? 
    • What’s the response cadence when sites reach out? 
    • Are sites bringing new gaps forward proactively, or only when prompted? 

    These metrics, taken together, tell you whether the corporate team has earned a real seat at the site’s table which is the precondition for everything else. 

    The Rebrand: From Auditor to SME Hub 

    If the corporate team has historically been seen as an auditing body, the shift to a pull system requires a deliberate rebrand. Sites won’t pull from a team they’ve learned to avoid. The team has to make itself visibly available and useful before sites will engage. 

    Two concrete moves: 

    Build a capabilities handbook. Create a directory of every SME on the team, bios, areas of expertise, the kinds of problems they’ve helped solve. Publish it on a SharePoint or internal portal where site leaders can browse it. The message: here’s what we know how to do; reach out when one of these is the gap you’re trying to close. 

    Ask the question. In every meeting with a site leader, end with a version of: “What’s one thing our team could do differently, starting next week, that would make you more likely to call us for support when you have a gap?” Listen to the answer. Act on it. The fastest way to be more useful is to ask the people you’re trying to serve what useful looks like to them. 

    The rebrand isn’t a poster or a new tagline. It’s the accumulated effect of a hundred small interactions where the team showed up as a resource rather than as a regulator. 

    Accountability Still Exists 

    A pull system is not a permission slip for sites to ignore corporate work. Accountability still lives in the system; it just lives in the right place. 

    When a site’s plan isn’t producing the results they committed to, governance has a responsibility to say so clearly. Not punitively, but accurately. “Site X committed to closing this gap by Q2. The gap is not closed. Here’s the current status, and here’s what support has been offered.” That’s an honest report, and it belongs in the conversation between your management chain and theirs. 

    The key is that escalation comes after genuine support, not instead of it. The corporate team’s first move when a site is struggling is to offer help, not to escalate. Only if the help is rejected and the commitment is repeatedly missed does escalation become the right move. And even then, the conversation is at the leadership level, not the SME level because the principle from the second post in this series still applies. 

    Accountability that flows through site-owned commitments and corporate-supported execution is durable. Accountability imposed by external mandate is theatrical, and it always reverts to compliance behaviors over time. 

    A Pull System Has to Be Earned 

    A pull system can’t be manufactured. It can’t be declared by a memo or rolled out as an initiative. It has to be earned, one problem solved at a time, one site relationship at a time, one piece of helpful work at a time. 

    The good news is that it can be earned. Sites are not actually hostile to corporate teams. They’re hostile to corporate teams that show up as additive work without offering anything in return. When a corporate team shows up as a resource, visibly useful, actually solving problems, accepting prioritization decisions, working at the right peer level, the relationship inverts. Sites start calling. Standards start getting adopted. Outcomes start moving. 

    If you’ve read this series and recognized your own team in the diagnosis, the path forward is concrete. Start with a few small moves. A charter conversation with one site, a site-led review meeting in place of a corporate-led one, an open-issue mechanism with a single pilot site, a capabilities handbook posted on the portal. Earn a few wins. Build credibility. The pull system grows from there. 

    The push model is the default. The pull model is the discipline. Most corporate teams fail because they never make the switch. The ones that do make it become the kind of corporate function that operating sites actually want to work with and that, more than anything else, is what determines whether the team’s work has any real impact at the end of the year. 
  • Your Peer Group Is Not Your Working Group: The Hardest Rule for Corporate Teams With Indirect Influence

    Your Peer Group Is Not Your Working Group: The Hardest Rule for Corporate Teams With Indirect Influence

    This is the second in a three-part series on how corporate teams without direct authority over the operating sites can actually succeed in driving adoption and change. The first post diagnosed the failure mode; compliance theater driven by a default push model. This post tackles the single most counterintuitive principle for corporate teams trying to escape that pattern. 

    Of all the rules I share with corporate functional leaders trying to influence sites without authority over them, this one gets the most pushback in the room and delivers the most value when actually applied: 

    Your peer group is not your working group. 

    Most corporate teams get this exactly wrong, and the misalignment is invisible to them until someone calls it out. Once you see it, you can’t unsee it. 

    The Mistake 

    Here’s how it almost always plays out. 

    A corporate team is developing a standard, a maintenance and reliability standard, an EHS standard, a quality SOP, an IT governance document, anything that requires technical accuracy and site adoption. To validate the standard’s technical content, the team identifies a subject-matter expert at each site. The site SME reviews drafts, provides input, signs off when the document is technically correct. 

    So far, so good. SME involvement in standards development is right. The mistake comes after the standard is published. 

    The corporate team continues working with the same SME. They follow up on adoption progress with the SME. They escalate when adoption stalls to the SME. They send reminders to the SME. They build their dashboards around what the SME is doing or not doing. The SME becomes the corporate team’s day-to-day point of contact for everything related to that standard. 

    This feels right. It feels efficient. The SME is the person who understands the technical content; surely they’re the right person to drive it forward. And if the standard isn’t being adopted, it must be the SME’s fault for not pushing harder. 

    It’s wrong. And it’s the single biggest reason corporate teams burn out trying to drive change at the site level. 

    Why Working at the SME Level Doesn’t Work 

    The SME at the site is not your peer. They don’t report to you. You don’t report to them. They have a day job that has nothing to do with your standard, assigned by a manager who has nothing to do with your standard. Their authority to allocate resources at the site is limited or nonexistent. 

    When you push them on adoption, you’re asking them to do something they can’t actually deliver on their own. They can’t reassign techs to your initiative. They can’t reorder the site’s project priorities. They can’t pull capital out of one bucket to fund the work your standard requires. Those decisions belong to the site leadership. 

    So when adoption stalls, the SME has two options. Option one: tell you the truth that the standard is fifteenth on the site’s priority list and won’t get worked until next year. That’s a hard conversation, and most SMEs don’t have the political room to have it. Option two: say something vague about timing and resources and quietly hope you stop calling. 

    Option two wins almost every time. Which is why corporate teams who work at the SME level spend their days chasing ghosts. 

    You’re not building accountability when you push the SME. You’re building avoidance. And you’re misallocating your own time, because the conversation that actually changes anything isn’t happening with the SME, it’s happening at the site leadership level, in rooms you’re not in. 

    The Boulder Uphill 

    I describe working at the SME level as pushing a boulder uphill. It feels productive, there’s motion, you’re talking to someone, the SME is nodding along but the boulder is heavy and the slope is steep, and the moment you stop pushing, it rolls back down. 

    Why? Because the SME has no leverage. Even when they want to help you, they don’t control the priorities. Their manager does. The site leader does. The local leadership team does. So whatever momentum you build with the SME evaporates the moment they walk into a meeting with their boss to talk about the actual operational priorities. 

    You can spend a career pushing this boulder. Many corporate teams do. They burn out, they get cynical about the sites, they conclude that the sites are uncooperative or undisciplined or unwilling to follow standards. None of that is the diagnosis. The diagnosis is that they’re working at the wrong level. 

    The Real Peer Group 

    Your peer group, as a corporate functional leader, is the site leadership. The plant manager, the operations director, the site general manager, whatever the title is in your organization. That’s the person who controls priorities, resourcing, and adoption sequencing. That’s the person who, when they decide to allocate resources to your standard, makes adoption actually happen. 

    Your job isn’t to convince the SME to push harder. Your job is to be useful enough at the site leadership level that when site leadership prioritizes their twelve competing initiatives, your work makes the cut. 

    This is a fundamentally different conversation than the one you’re having with the SME. It’s strategic. It’s about business outcomes the site leader is accountable for, not technical specifications the SME signed off on. It’s about how your standard helps the site hit their numbers, production, safety, quality, cost but not about whether it’s been incorporated into local documentation. 

    When you have that conversation with the right person, two things happen. Either site leadership says, “Yes, this is a priority, and here’s what we’ll commit to,” and adoption follows naturally. Or they say, “I hear you. We have twelve initiatives competing for resources right now, and your work is twelfth on the list.” Either answer is useful. Both are honest. Both let you stop pushing the boulder. 

    The Discipline of Being Twelfth on the List 

    Here’s the part that’s hard to accept: when site leadership tells you you’re twelfth on their list, the right response is to accept it. 

    I know that’s hard. You spent six months developing the standard. You believe in its importance. You can articulate why it matters. And being told it’s twelfth feels like being told it doesn’t matter at all. 

    But the discipline is to accept the prioritization, report your status accurately, and keep showing up. Don’t escalate around the site leader. Don’t try to leverage your management chain to override their priorities. Don’t pivot back to working at the SME level because you can’t get traction at the leadership level. None of that helps. 

    What helps is to keep reporting. “Standard X is at twelfth priority at Site Y; estimated adoption window is Q3 next year.” Keep doing that month after month. Eventually one of three things happens: 

    1. The site leader’s priorities shift naturally and your standard moves up the list as resources free up. 
    1. Your management chain decides the prioritization is wrong and engages with theirs to renegotiate it. That’s a leadership-to-leadership conversation, and it gets handled at the right level. 
    1. The standard remains low priority indefinitely because the site has bigger problems to solve. That’s also a valid outcome and it tells you something about whether your standard was actually solving the most important problems. 

    In all three cases, you’ve stayed in your lane, maintained credibility with the site leader, and avoided burning your relationship by pushing on someone who didn’t have the authority to act anyway. 

    There’s also a competitive consideration here. If your team is one of many corporate teams pushing standards at the same sites and most teams are, you’re sharing a finite pool of local resources with the other corporate functions. Trying to force your standard up the priority list ahead of someone else’s doesn’t actually help your team. It just trades short-term adoption of your work for long-term resentment from the site. Accepting the priority list is the discipline that lets the network of corporate teams collectively succeed instead of cannibalizing each other. 

    The Asset-Centric Reframe 

    Underneath this principle is a deeper reality about how operating companies work. The company buys assets to add value. Production lines, processing units, distribution networks, IT infrastructure — whatever the assets are, that’s where money is made. The people who operate and maintain those assets are the ones generating value. Everyone else in the company is a support function whose job is to help those frontline people get more value from the assets. 

    That includes corporate teams. 

    If a corporate team isn’t visibly helping the sites get more value from their assets. Fewer breakdowns, less waste, lower risk, faster throughput, better quality, that team is optional. It might not feel optional from inside the team. The work feels important, the standards feel necessary, the governance feels real. But from the site’s vantage point, if you’re not making them better at running their assets, you’re overhead. 

    This is a hard truth, and it’s the one that makes the peer group principle actually land. The reason your peer is the site leader, not the SME, is because the site leader is accountable for getting value from the assets. They’re the customer your team exists to serve. The SME is a contributor to your work product; the site leader is the recipient of it. You serve the recipient, not the contributor. 

    When corporate teams internalize this, the dynamic changes. They stop trying to enforce adoption and start trying to be useful. They stop tracking SME compliance and start tracking site outcomes. They stop pushing boulders and start solving problems. 

    What This Looks Like in Practice 

    A few concrete behavioral shifts to apply this principle: 

    • Identify your peer group explicitly. Make a list of the site leaders for every site your team supports. That’s who you’re really working for. The SMEs are colleagues, not customers. 
    • Cadence with site leadership matters more than cadence with SMEs. Build a regular touchpoint with site leadership. Quarterly business review, monthly check-in, whatever fits the rhythm. That’s the venue where your work actually moves. 
    • Talk in business outcomes, not standards. When you’re with site leadership, stop talking about whether the standard has been adopted. Start talking about what the standard is helping them solve, the safety incident rate, the unplanned downtime, the quality defect rate. Outcomes are their language. 
    • Accept the priority list. Whatever ranking your standard gets, accept it. Report against it. Don’t try to renegotiate it through informal channels or by pressuring people who don’t have authority. 
    • Move escalation to the right level. If a standard genuinely needs to move up the list, that conversation happens between your management chain and theirs but not between you and the SME. 

    The Permission to Stop Pushing 

    If there’s one outcome, I want corporate teams to take from this principle, it’s the permission to stop pushing the boulder. You’re not lazy when you accept that you’re twelfth on the list. You’re not failing when you decline to escalate around a site leader. You’re being honest about where the authority actually lives, and you’re saving your team’s energy for the work that genuinely moves the needle and being useful at the site leadership level. 

    Corporate teams that learn this principle become dramatically more effective. They stop chasing accountability that isn’t theirs to enforce. They stop building dashboards that track activities instead of outcomes. They stop burning out trying to drive change through the wrong people. As a side effect, the relationship with the sites improves because the sites stop feeling pushed. 

    Your peer group is the site leader. The working group is just the team that helps build the work product. Don’t confuse the two, and don’t try to manage one as if they were the other. 

    The next post in this series gets into the practical mechanisms. The operating cadence, the measurement framework, and the rebrand from auditor to problem-solver, that turn this principle into a functioning system.